Code that only compiles proves little. That is true of examples, and equally of tests, benchmarks, fuzz targets and fixtures. Anything in the repository that is not run goes stale without anyone noticing, and is found broken on the day it is needed.
The rule is that every Roc program in the repository runs in pull-request CI, even if only briefly. This chapter says what runs, how much of it, and how the tests are organised.
Start with expect tests for concrete behavior and integration cases for the
program boundary. Use roc-fuzz alongside them to check rules over generated
inputs, preserve named regressions and measure memory behavior. Pure Roc code
needs both value correctness and allocation properties: returning the right
value does not show whether an update reused storage or copied it. Keep these
checks fast on pull requests, and explore new inputs in separate campaigns.
Risks and controls for test evidence§
Compilation alone can leave examples or error paths broken, while a long campaign in routine CI can make feedback too slow to use. Keep fast checks meaningful and put sustained searches on their own schedule. Build once, run recorded success and failure cases, and exercise bounded fuzz/benchmark smoke modes. Require expected outputs and exits, report skips explicitly, retain command diagnostics and stop hung child trees. The driver tests these failure states. A smoke pass establishes that the selected workload runs; it does not establish search depth, performance or complete test coverage.
What runs on every pull request§
| Check | What it runs |
|---|---|
| Formatting | roc fmt --check over the repository’s Roc sources |
| Unit tests | roc test on the package or platform root |
| Examples | Every example, built once and run against its recorded cases |
| Integration tests | The test driver, over its full list of cases |
| Allocation checks | Allocation properties and recorded examples, checked against reviewed ceilings or accepted exact baselines |
| Benchmarks | A smoke run: each benchmark builds and completes a small, bounded iteration |
| Fuzz targets | A smoke run: each target builds, checks its declared examples and replays a small committed corpus |
| Scripts | The expect tests of the modules under scripts/src/ |
The check task runs all of these, so a contributor runs the same set with
blueprint run check before opening a pull request.
Heavy runs stay out of pull-request CI§
A long fuzzing campaign or a full benchmark run never runs on a pull request, including a release dry run. They run in separate scheduled or manually dispatched jobs, as described in Fuzzing and Benchmarks.
What pull-request CI owes them is a smoke run. A benchmark that has not been built since the API it measures changed will not run on the night it is scheduled. Give each benchmark and fuzz target an explicit smoke mode, with a small input or iteration count and at most one second of workload execution per target. This budget excludes provisioning and compilation; it is not a one-second limit for the whole CI job. Keep the committed smoke corpus small enough to replay within that budget. Build once and reuse the executable across cases.
The smoke mode exercises startup and the real operation or property, then exits normally. A benchmark smoke run checks execution, not performance: it produces no baseline comparison or performance regression verdict. A fuzz smoke run replays known inputs; where the engine itself needs exercising, add a tiny, bounded run without turning the check into a campaign. A passing smoke run makes no claim about sustained search coverage.
Workload bounds and safety deadlines serve different purposes. Set a small iteration/input budget so normal execution completes within the smoke budget, and give the driver a separate hard deadline to stop hangs and child processes. A crash, wrong result or exceeded deadline fails the smoke check; stopping a process at the deadline does not establish success. Preserve compiler and workload diagnostics even on successful commands, with warnings nonfatal by default. Print explicit skips with reasons; skipped work is not passing compatibility evidence.
Keep the long-running task out of blueprint run check and every PR release
dry-run path. Moving it into another job is insufficient if that job still
runs on every pull request: use schedule/manual triggers and explicit event
guards. The routine PR aggregate requires the build and smoke jobs, not a
skipped campaign job.
Build with --opt=dev§
Build and run with --opt=dev unless there is a reason not to. It compiles
quickly, which is what a test run spends most of its time on, and the checks in
this chapter ask whether the program is correct, not how fast it is.
Use --opt=speed only where the optimised build is the thing under test: a
benchmark’s measured run, a long fuzzing campaign, or a release artifact that
ships optimised. A benchmark’s smoke run in pull-request CI uses --opt=dev
like everything else.
Unit tests§
Run roc test once, on the root: package/main.roc for a package,
platform/main.roc for a platform. Roc runs the expect tests of every module
the root imports, transitively, so there is no need to list files or to run the
command per module. A module that the root does not reach is either dead code or
missing from the package, and either is worth knowing.
A repository with several roots runs roc test once on each.
Integration tests§
An integration test runs a built program and looks at what it does: its output, its exit code, the files it writes. Organise these around an external driver and a list of cases, not as one program per test.
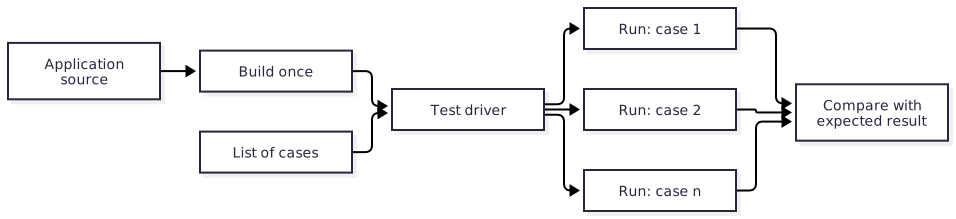
Build once. The driver builds the application a single time and runs the resulting executable for every case. Compiling dominates the cost of a test run, so this is the difference between a suite that takes seconds and one that takes minutes.
Cases are data. Each case names its arguments, its standard input, any files it needs, and the expected output and exit code. Adding a case is adding an entry, not writing a program.
Cover failure as well as success. The same executable is run on the error paths: bad input, missing files, invalid arguments. A case that expects a particular error message and a non-zero exit code is as ordinary as one that expects success.
The driver owns the environment. Because it sits outside the program under test, the driver decides how cases run. It can give each case its own process and working directory, run cases in parallel, set up and tear down what a case needs, and apply a timeout. None of that leaks into the application.
An update mode. The driver accepts
--updateto rewrite expected results, so an intended change in behavior is a reviewed diff.
The driver is a Roc script under scripts/, and the cases live under tests/.
The expected-output specification for examples, described in
Record expected output, is one such
list of cases run by the same driver.
Skip a broken case, visibly§
Sometimes a case is broken for a reason that cannot be fixed today: a compiler bug, a dependency that has not been released, a platform limitation. Deleting the case loses it, and leaving it failing blocks every pull request. Skip it, and make the skip impossible to forget.
Mark the skip where the case is defined, with a
TODOnote and a link to a GitHub issue that tracks the cause.# TODO: skipped until the compiler handles nested tag unions here. # https://github.com/roc-lang/roc/issues/<number> { name: "nested-tags", skip: Skip("compiler bug, roc-lang/roc#<number>"), ... }A skip always carries a reason. The harness rejects a skip with no note.
The harness prints every skipped case with its note, and counts skips in the summary. Nobody should have to search the source to learn what is not being tested or why.
A skip is temporary. When the linked issue closes, the skip is removed in the pull request that confirms the case passes again.
The same applies outside the harness: an example, benchmark or fuzz target that
is switched off says why, in a TODO with an issue link, at the place it is
switched off.
Report progress and results§
A harness is read far more often than it is written, usually by someone waiting for it or trying to find out what failed. Its output is part of its job.
Running 20 cases
 [ 1/20] parse-empty-input ............ PASS      12ms
 [ 2/20] parse-nested-lists ........... PASS      48ms
 [ 3/20] render-wide-table ............ FAIL   1_204ms
 [ 4/20] nested-tags .................. SKIP          compiler bug, roc-lang/roc#1234
 ...
 [20/20] rejects-missing-file ......... PASS       9ms

Failed
  render-wide-table: expected exit code 0, got 1
    tests/cases/render-wide-table

Skipped
  nested-tags: compiler bug, roc-lang/roc#1234

Summary: 18 passed, 1 failed, 1 skipped in 10_312ms
Slowest: render-wide-table 1_204ms, build 6_870ms
Show progress as it happens. Print each step with its position, such as
3/20, and its result as soon as it finishes. A run that prints nothing for a minute looks the same as a run that has hung.End with a summary. Report how many cases passed, failed and were skipped, list each failure with enough detail to act on, and list each skip with its note. The summary is what a reader sees first in a CI log, so it stands alone.
Report timing. Give the time of each case, the total, and the slowest steps, including the build.
Use one unit for time. Print every duration in milliseconds, with digit separators and aligned to the right:
12ms,1_204ms,10_000ms. With a single unit the eye compares lengths, and a slow case stands out. A column that mixes850ms,1.2sand2mhides exactly the outlier worth seeing.Use color.
FAILis red,PASSgreen,SKIPyellow. Color is an aid and never the only signal: the word is always printed, and color is turned off when output is not a terminal or whenNO_COLORis set.Exit accurately. Any failure gives a non-zero exit code. Skips alone do not.
Measure allocations§
Memory behavior is a quality of Roc code in its own right, and it is invisible unless it is measured. A change that keeps a reference alive a little longer can turn an in-place update into a copy of a whole list, on every call. The result is still correct, every test still passes, and the package is now several times slower for its users.
Use roc-fuzz as a test platform for pure package code. Its host measures allocations, reallocations, deallocations, requested bytes and live/peak memory. Test the hot paths and operations users call in a loop, including empty, boundary-sized, uniquely owned and shared inputs.
Allocation properties and exact baselines§
Use two complementary checks:
Properties over inputs. Assert a memory rule inside the target, such as "this operation allocates nothing" or "this update performs at most one allocation or reallocation". The assertion runs for declared examples, replayed inputs and generated inputs. Use
Fuzz.expect_allocs_at_most!for a ceiling, or use a namedFuzz.measure!region and inspect its statistics for a more specific rule. A measurement returns{ value, stats }, so correctness and memory behavior can be checked together.Exact observations for named examples. Declare representative cases with
Fuzz.example({ name, revision, make: || value }), or preserve a witness withFuzz.saved({ name, revision, bytes }). roc-fuzz checks each in a fresh process and compares its allocation observations with an explicitly accepted baseline. Named measurements isolate operations within the property.
These checks have different review rules. A ceiling fails only when the count exceeds the bound; lower it when an improvement should be protected. roc-fuzz’s baselines match exactly, including example inventory, revisions, actual input digests, measurement regions, metric version and statistics. Reductions also require review and explicit acceptance. A compiler improvement should therefore update a baseline deliberately, rather than silently changing what CI accepts. Commit baselines for each supported host and named profile; record the compiler and build options with the evidence.
check verifies examples and accepted baselines without exploration. A missing
entry is reported as unbaselined and permits normal execution; it is not
allocation regression protection. Review the declared inventory and measurements,
run accept explicitly, and commit the resulting baseline before treating
checks as evidence of a protected allocation contract. CI runs check or run,
never accept.
Allocation evidence depends on the measured scope and storage shape. roc-fuzz
measures the property after input generation/decoding and before adapter teardown;
named regions narrow that scope further. Keep aliases alive when testing shared
storage, and observe returned values so the intended operation remains relevant.
A logically equal value can have different capacity, sharing or slices. Preserve
original witness bytes for storage-sensitive failures: reconstructing a value
in an expect test may lose the allocation behavior that exposed the bug.
Counts are a steadier PR signal than wall-clock timings, but they depend on the
compiler, host, build and lifetime of values. Review baseline diffs alongside
correctness results, and use a deliberate failing assertion or changed baseline
to verify that the harness detects a regression. A pass covers the checked
examples and explored inputs; it does not prove an allocation bound for all
inputs. roc-fuzz also supports logical trace rules (Before, Count and
Forbidden) for ordering and event invariants. These are logical observations;
wall-clock performance belongs in the separate benchmark workflow.
Correctness and memory properties with roc-fuzz§
Use property-based tests for invariants across inputs, especially parsers, encoders, data structures and arithmetic on sizes or indexes. roc-fuzz combines correctness, allocation and trace checks with coverage-guided exploration in a self-contained Roc target. The target imports the package; the shipped package has no dependency on roc-fuzz.
| Part | Role |
|---|---|
| Generator | Produces typed Roc values to try: numbers, strings, lists, records, or shapes built from them |
| Operation | Calls the package code under test |
| Property | Checks value correctness, memory behavior or a logical invariant |
| Examples | Named cases and saved witnesses that run independently of corpus retention |
A pure function needs no external state to recreate. Useful properties include round-trip encoding, formatting idempotence and agreement with a simple reference implementation. Preserve failing input bytes and the target/compiler/build configuration, especially for storage-sensitive memory checks. Coverage guides exploration toward new branches; saved witnesses and named examples preserve regressions independently of the evolving corpus.
What a target looks like§
app [target] {
	fuzz: platform "https://github.com/lukewilliamboswell/roc-fuzz/releases/download/<version>/<hash>.tar.zst",
	pkg: "../../package/main.roc",
}

import fuzz.Fuzz
import pkg.Stack

# After pushing an item, popping must return that item and the original stack.
test : List(U8) -> Fuzz.Outcome
test = |initial| {
	item = 0
	pushed = Stack.push(initial, item)

	match Stack.pop(pushed) {
		Ok({ value, rest }) if value == item and rest == initial => Fuzz.keep
		Ok(_) => crash "pop did not undo push"
		Err(Empty) => crash "the stack was empty after push"
	}
}

target = Fuzz.target_with({
	examples: [
		Fuzz.example({ name: "empty", revision: "1", make: || [] }),
		Fuzz.example({ name: "nonempty", revision: "1", make: || [1, 2, 3] }),
	],
	name: "stack-push-pop",
	generator: Fuzz.list(Fuzz.u8, 8),
	test,
	show: |initial| Str.inspect(initial),
})
The target depends on the working tree by relative path, like every other Roc
application in the repository, and on a roc-fuzz release by URL. It lives
under fuzz/, outside the package root, so it is never bundled. Use the
content-addressed platform URL and compatible compiler documented in the
release notes.
Build once, then use the commands embedded in the executable:
roc build --fuzz fuzz/stack/main.roc --output=stack-fuzz
./stack-fuzz check
# After reviewing the observations, explicitly accept and commit the baseline.
./stack-fuzz accept
./stack-fuzz check
# Local exploration; the default run searches for 60 seconds after checking.
./stack-fuzz run
check runs declared examples and baseline checks without searching. run
checks them before exploring, and skips exploration when those checks fail.
Use run --report-dir=PATH for campaign evidence; the report directory must be
absent or empty. Bare invocation also runs the default workflow, so PR tasks
must select check and bounded replay explicitly rather than accidentally
starting a 60-second search. The default baseline is
<declared-target-name>_baseline.json in the working directory; use
--baseline=PATH and --profile=NAME when needed.
For an allocation-aware target, use an effectful property and
Fuzz.target_with!. For example, popping a stack can check the returned
length while asserting that it performs no allocations or reallocations:
test! : List(U8) => Fuzz.Outcome
test! = |initial| {
	popped = Fuzz.expect_allocs_at_most!(0, || Stack.pop(initial))
	match popped {
		Ok({ value: _, rest }) if rest.len() + 1 == initial.len() => Fuzz.keep
		Err(Empty) if initial.is_empty() => Fuzz.keep
		_ => crash "pop returned the wrong length"
	}
}
Pass test! in place of test to Fuzz.target_with!, keeping the generator,
examples and display function. Replace the measured operation and property
with the package’s actual memory contract. The
roc-fuzz quality guide
explains named measurements, baselines, trace rules and report fields.
How targets are managed§
Review properties when APIs or implementations change. Strengthen invariants and generators as the input domain becomes clearer; add named examples for newly discovered failures.
Write one operation and one property per target, so that a failure says what went wrong.
Add a target when a module has a rule that should hold for all inputs. Every parser and every encode and decode pair should have one.
When roc-fuzz finds a bug, replay and minimise it, fix it, and use
retainto preserve the witness as a namedFuzz.savedexample. Add an ordinaryexpecttest for the value-level regression when useful. Keep original storage-sensitive witnesses even when a smaller logical example is available.Commit a small corpus for each target. Pull-request CI builds every target and checks its named examples and allocation assertions, accepted baselines and bounded corpus replay as its smoke run.
Run the real search on a schedule, as described in Fuzzing.
Validate preconditions for decoded examples as well as generated values; generator bounds express search bias, not input validation. Report attempted, accepted and rejected inputs. Exploration with zero accepted inputs is inconclusive and unsuccessful. Distinguish the outcome from allocation validity, trace-rule results and capture completeness in the evidence.
A weak property finds nothing, and a passing run is not a proof. The roc-fuzz manual covers writing generators and properties, running campaigns, and reading a saved failure.
Formatting§
Run roc fmt --check in pull-request CI, over every Roc source the package
compiler builds, and roc-stable fmt --check over the scripts, whose roc
field another compiler’s formatter would rewrite. It fails the pull request that introduces unformatted code, which is
the only moment at which fixing it is cheap.
Do not run it in nightly.yml. A new nightly can change the formatter, and a
formatting difference says nothing about whether a release still works. The
check would raise an alarm that no patch release answers. When a new formatter
does change the output, the next pull request sees it, and reformatting is a
small pull request of its own.